
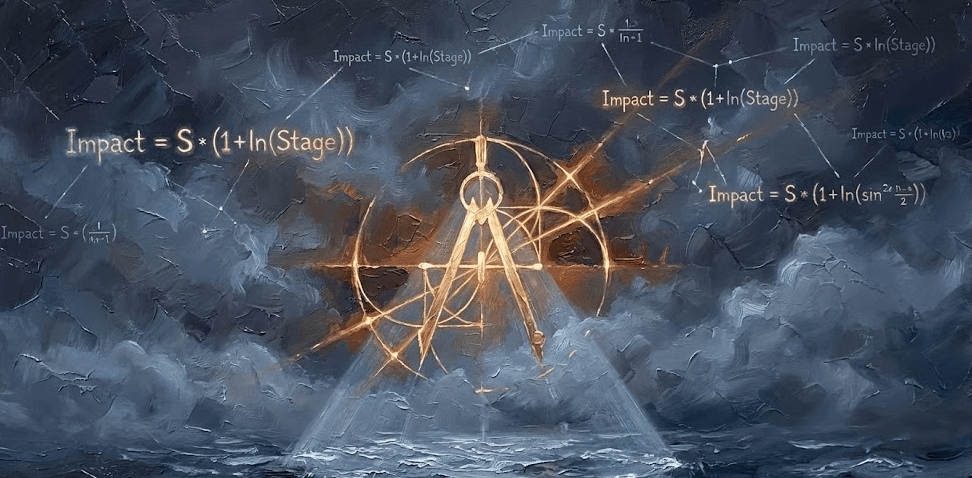
Series: 60-Day Gamble: Part 3Business Decision Science
When Silence Becomes Evidence
BA02.[App. 2] The Paradox of Silence: Entropy and the Geometry of Logarithmic Weighting
- Bayesian
- Likelihood
- Logarithmic Weighting
Evidence, methods, and operating insight for decisions that must work in the field.
BA02.[App. 2] The Paradox of Silence: Entropy and the Geometry of Logarithmic Weighting
This article explains the mathematical principles and effectiveness of the Bayesian engine covered in the [BA02 Episode]. The goal is to precisely predict sales success probabilities in an uncertain business environment. At its core, it addresses the process of deriving optimal decision-making indicators by combining the Beta distribution, which quantifies past experiences, and the Binomial distribution, which captures real-time signals from the field. In particular, it emphasizes maximizing the system’s real-time performance and computational efficiency by utilizing Conjugate Prior distributions, which allow for immediate updates without complex calculations. Furthermore, this model adopts a Recursive Estimation method that makes immediate judgments whenever data occurs, securing technical validity optimized for modern business. Consequently, this document clearly demonstrates how sophisticated mathematical modeling transforms vague intuition into reliable, data-driven insights.
An ExaWin+ decision case that updates field observations and customer responses as Bayesian evidence, tracks win probability over 60 days, and allocates limited sales resources to better customers and actions.
I chose Reinforcement Learning (RL) as the first topic of this blog because of my personal interest in a field that has developed from classical theory along a different trajectory from rapidly advancing deep learning and LLM AI agents, while continuing to influence the real world, and because reinforcement learning is also being integrated into Exa-Solution, Exavion’s extended ERP and AI-integrated enterprise application.
Many learners who are new to Reinforcement Learning struggle early on because they do not clearly understand the conceptual difference and relationship between the Markov Decision Process (MDP) and Reinforcement Learning (RL). To reduce this confusion, it is necessary to first clarify how the two concepts are related.